
SkyRL Blog
Engineering notes, research updates, practical guides and deep dives on post-training from the SkyRL community
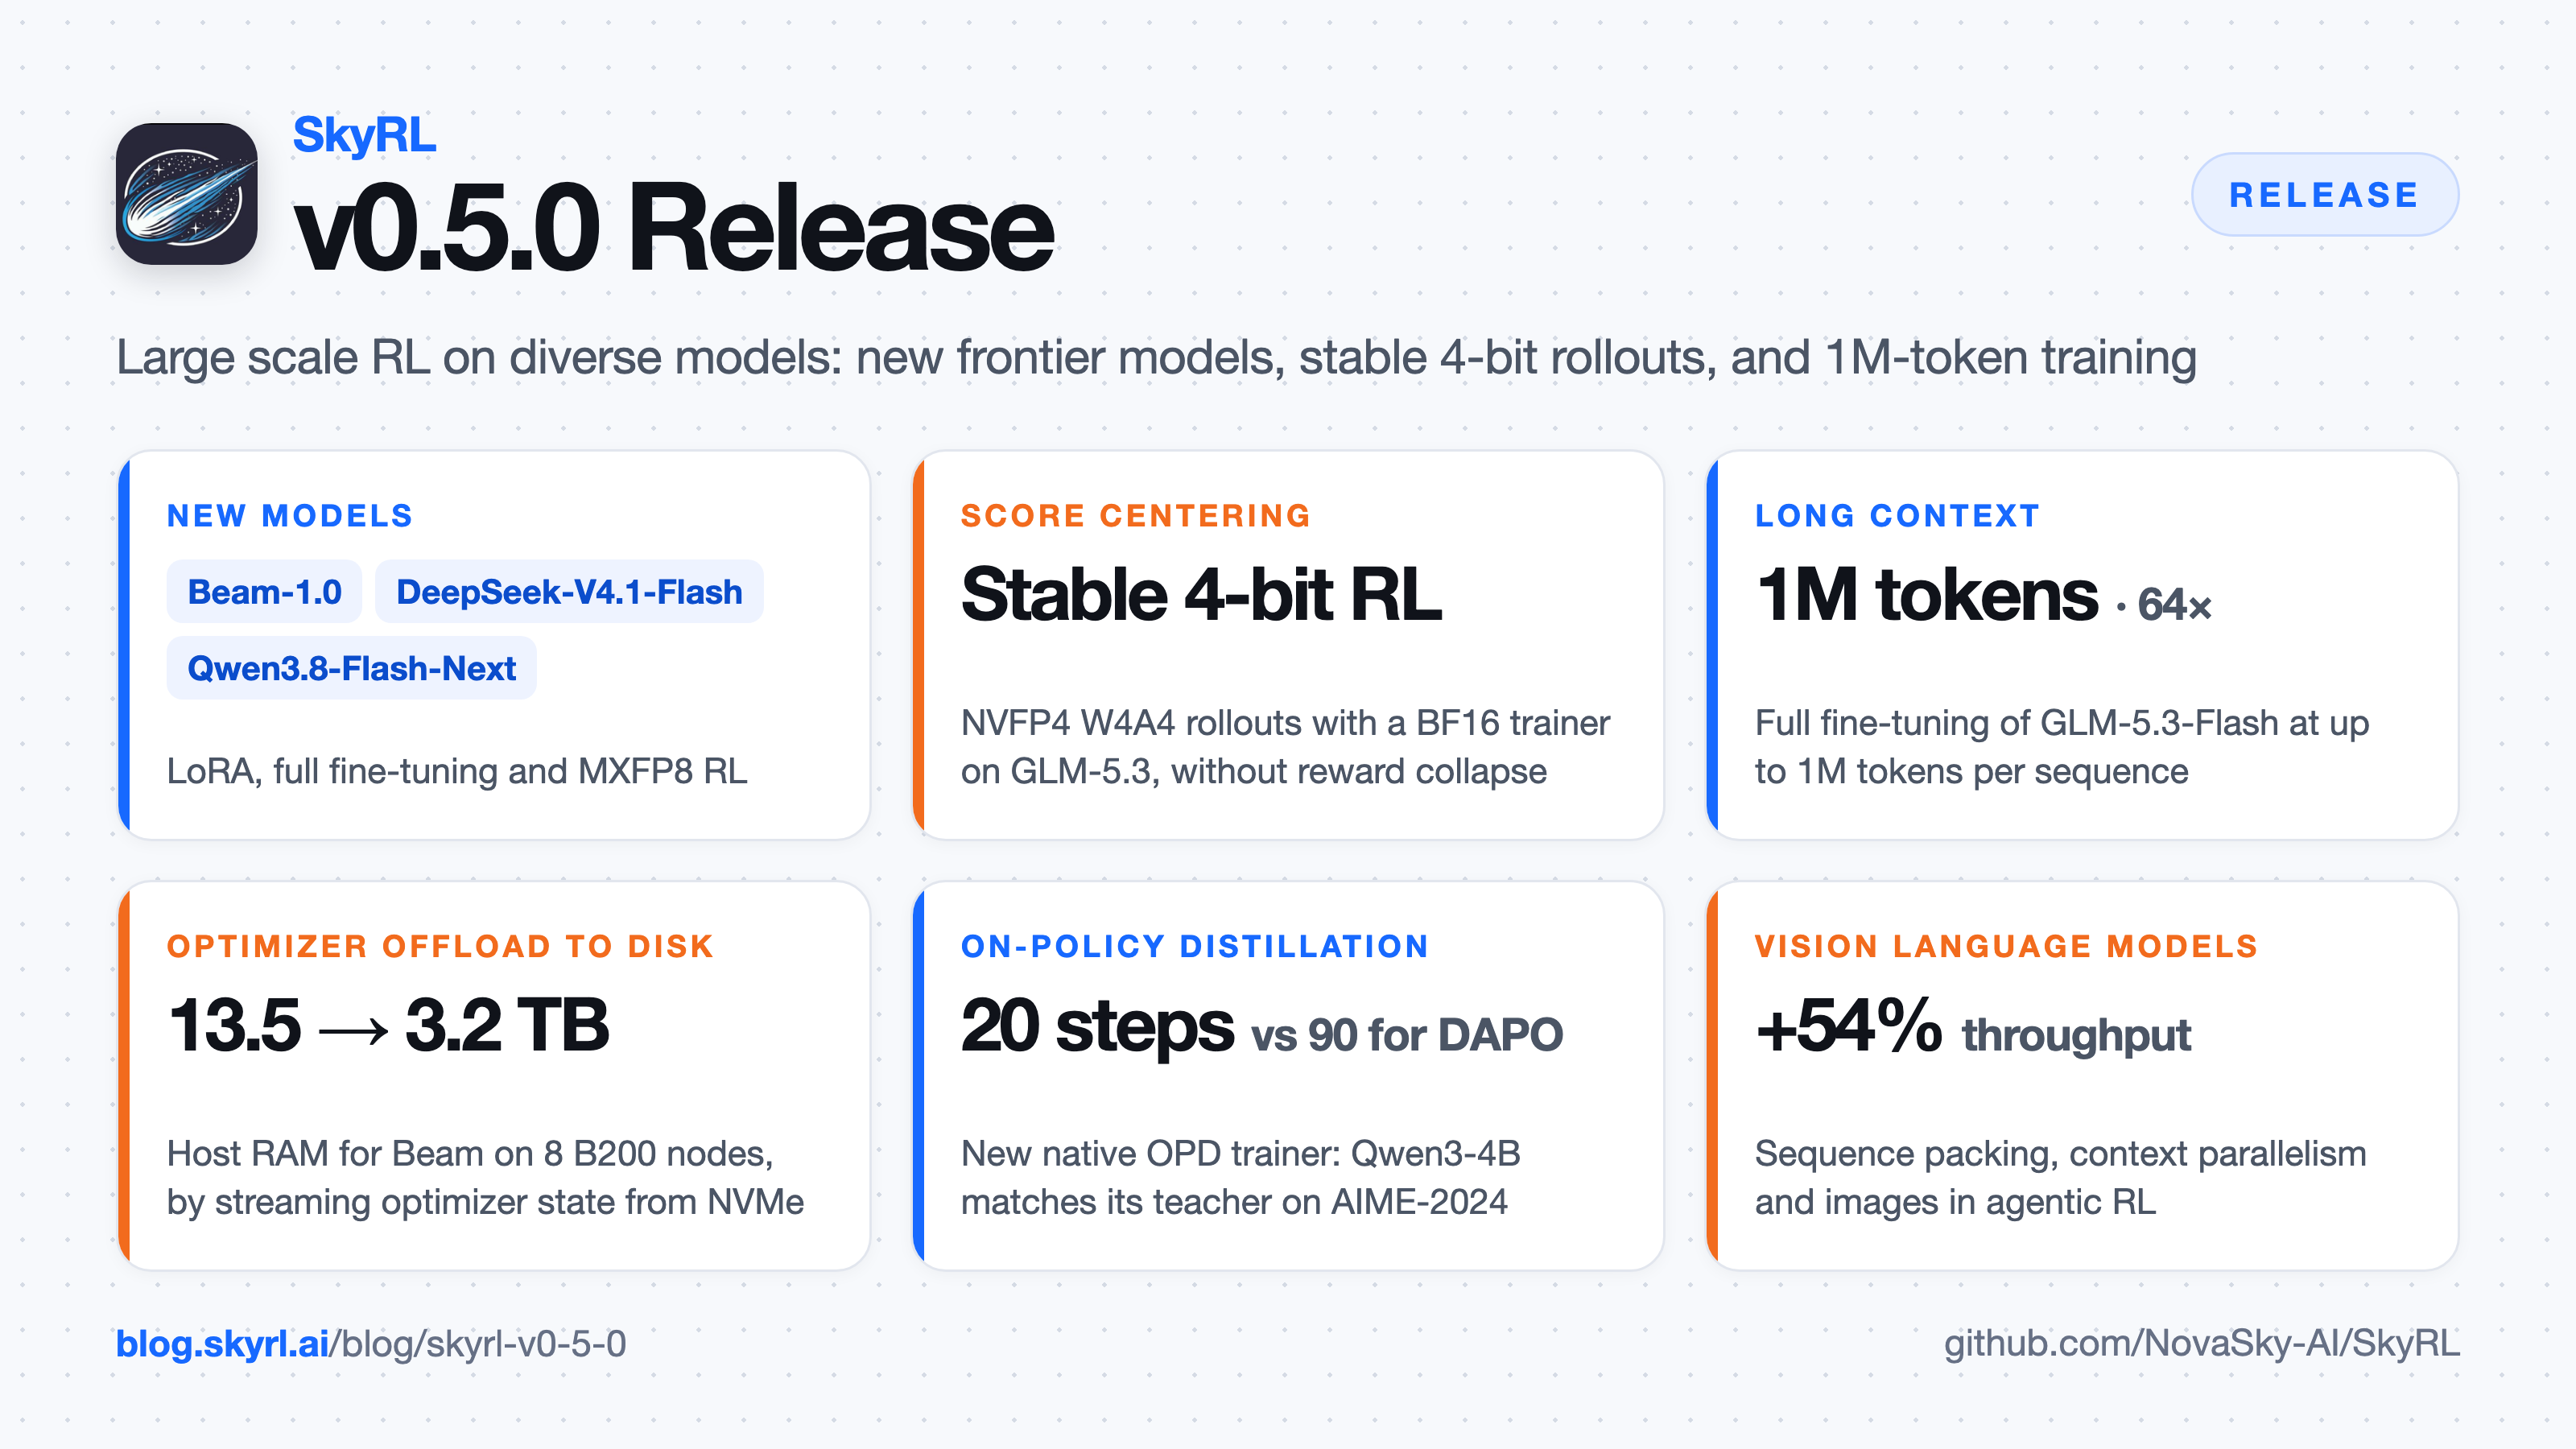
FEATURED · RELEASE
SkyRL v0.5.0: Large scale RL on diverse models
Support for Beam, DeepSeek-V4.1-Flash and Qwen3.8-Flash-Next, score centering for stable 4-bit rollouts, 1M-token context, optimizer offload to disk, a native on-policy distillation trainer and better VLM training.
LATEST ARTICLES
22 storiesSkyRL v0.5.0: Large scale RL on diverse models
Support for Beam, DeepSeek-V4.1-Flash and Qwen3.8-Flash-Next, score centering for stable 4-bit rollouts, 1M-token context, optimizer offload to disk, a native on-policy distillation trainer and better VLM training.
Scaling Training to 1M Token Context on GLM-5.3-Flash
SkyRL now trains GLM-5.3-Flash at 1M tokens per sequence, 64× the previous baseline, through sparse attention fixes, activation recompute and offloading, context parallelism and fewer fp32 upcasts.
Day 0 Support for Beam in SkyRL
Day 0 RL support for Beam. LoRA, BF16 full fine-tuning and MXFP8 RL are supported out-of-the-box, and we also upgraded SkyRL for efficient RL at 500B scale.
SkyRL v0.4.0: Improving SkyRL for large scale post-training
New model support, more stable RL, faster routing replay, efficient weight transfer, and a stronger path to production-scale experiments.
Training frontier knowledge work agents: A 397B RL training guide with SkyRL
A step-by-step guide to post-training Qwen3.5-397B-A17B with SkyRL, including the infrastructure, systems tuning, and lessons behind the hero run.
SkyRL v0.3: The open stack keeps moving
The latest SkyRL milestone and what comes next for open, full-stack reinforcement learning.
SkyRL TX Release — February 2026
A release update covering the latest progress in SkyRL TX and tool-using agent research.
SkyRL Harbor: A home for agent environments
An environment layer for bringing richer tasks and real-world interaction into agent RL.
SkyRL Tinker: Faster iteration for RL researchers
Making it easier to prototype, debug, and iterate on reinforcement learning ideas.
SkyRL TX v0.3.0: Toward dependable agent RL
A new TX release with improvements for dependable, scalable training workflows.
SkyRL TX v0.2.1: Refining the training loop
A focused update that improves the day-to-day experience of running TX experiments.
SkyRL TX v0.2: Advancing scalable agent training
New capabilities for scaling experiments across environments, tools, and model families.
On-policy distillation for capable language agents
A practical look at distilling strong behaviors into models through on-policy training.
SkyRL TX v0.1.0: A new milestone for tool-use RL
The first major TX release brings a more complete foundation for training tool-using agents.
SkyRL TX 0.0.3: More reliable experiments
Updates to the TX stack for reproducible, production-minded reinforcement learning research.
SkyRL TX v0.0.2: Iterating on agent training infrastructure
An incremental release focused on making agent training workflows easier to run and extend.
SkyRL TX: Scaling training for tool-using agents
New infrastructure for efficient reinforcement learning with tool use and external environments.
SkyRL DeepResearch: Long-horizon research agents
A look at the systems and training recipes behind capable research-oriented agents.
Search-R1: Training reasoning models to search
Exploring reinforcement learning for agents that learn when and how to search for information.
SkyRL v0.1: Building a stronger foundation for agent RL
The next step in making full-stack reinforcement learning research more modular and reproducible.
SkyRL SQL: Reinforcement learning with structured data
Training agents to reason over databases, structured data, and reliable tool interactions.
SkyRL v0: Train real-world long-horizon agents via reinforcement learning
Introducing SkyRL v0, an open framework for training capable long-horizon agents with reinforcement learning.